ECIR 2025 · Conference paper
Patent Figure Classification Using Large Vision-Language Models
European Conference on Information Retrieval, ECIR 2025, Lucca, Italy, April 6-11, 2025, pp. 20–37. Springer Nature Switzerland.
Abstract
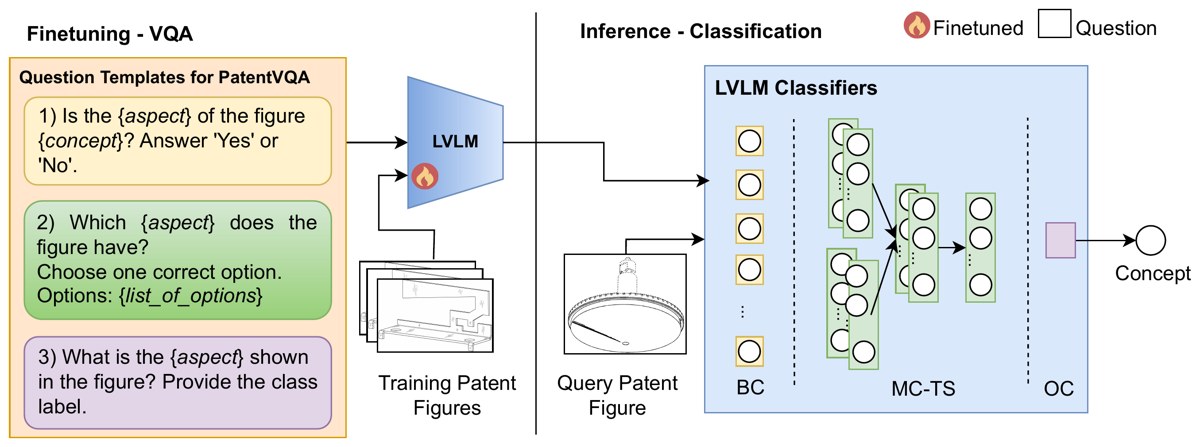
Patent figure classification facilitates faceted search in patent retrieval systems, enabling efficient prior art search. Existing approaches have explored patent figure classification for only a single aspect and for aspects with a limited number of concepts. In recent years, large vision-language models (LVLMs) have shown tremendous performance across numerous computer vision downstream tasks, however, they remain unexplored for patent figure classification. Our work explores the efficacy of LVLMs in patent figure visual question answering (VQA) and classification, focusing on zero-shot and few-shot learning scenarios. For this purpose, we introduce new datasets, PatFigVQA and PatFigCLS, for fine-tuning and evaluation regarding multiple aspects of patent figures (i.e., type, projection, patent class, and objects). For a computational-effective handling of a large number of classes using LVLM, we propose a novel tournament-style classification strategy that leverages a series of multiple-choice questions. Experimental results and comparisons of multiple classification approaches based on LVLMs and Convolutional Neural Networks (CNNs) in few-shot settings show the feasibility of the proposed approaches.
Cite
@inproceedings{awale2025patfig,
  author = {Awale, Sushil and M{\"u}ller-Budack, Eric and Ewerth, Ralph},
  title = {Patent Figure Classification Using Large Vision-Language Models},
  booktitle = {European Conference on Information Retrieval, {ECIR} 2025, Lucca, Italy, April 6-11, 2025},
  pages = {20--37},
  publisher = {Springer Nature Switzerland},
  year = {2025},
  doi = {10.1007/978-3-031-88711-6_2},
  month = apr,
}